Suffix Cache Reuse
A KV cache policy that reuses cached states after a mid-context edit, not just before it, by shifting their positions. It was introduced in the Context Language Models paper (Shao et al., 2026), where the model edits its own context and would otherwise lose most of its cache.
Serving engines like SGLang reuse cached keys and values for the longest prefix that matches the previous request. Appending keeps the whole prefix, but an edit in the middle forces everything after it to be prefilled again.
If the context A B C becomes A B' C, standard prefix caching keeps A and recomputes B' and C. Suffix Cache Reuse (SCR) also keeps the cached states for C, shifts their rotary position encodings to the new positions, and only prefills B'.
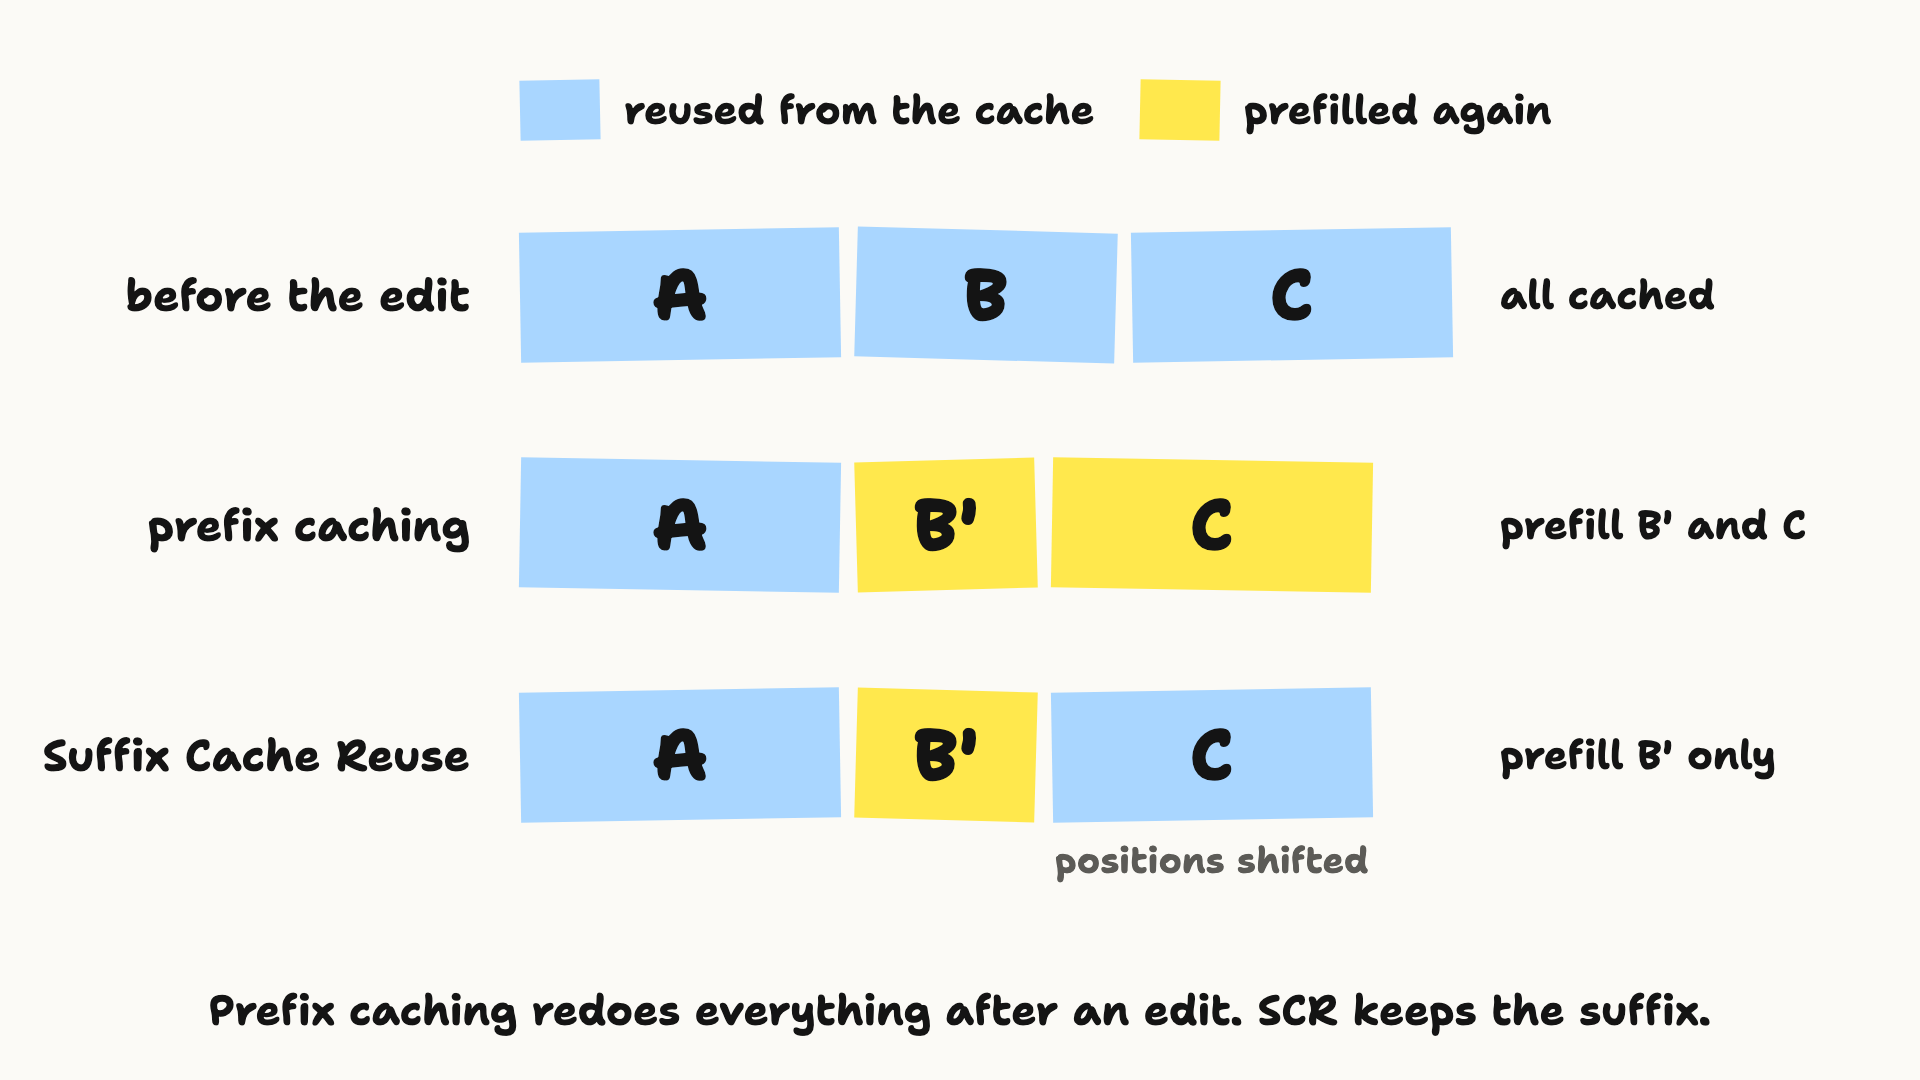
It's an approximation, because the states for C were computed with B in front of them, not B'. To limit how much approximation one edit can introduce, SCR reuses at most the six longest surviving spans per edit and prefills the rest.
On BrowseComp-Plus with Qwen3.6-27B, SCR matched standard SGLang's accuracy (60.2%) using 65% of its FLOPs. It also helps ordinary chat serving. Reasoning models' chat templates strip the thinking from earlier turns, which is also a mid-context edit, and most of SCR's extra cache reuse (5.3 of 7.8 percentage points of prompt tokens) came from that rather than from the model's own edits.
References
Rulin Shao, Shannon Zejiang Shen, Junjie Oscar Yin, Yuetai Li, Minheng Wang, Hamish Ivison, Radha Poovendran, Nathan Lambert, Teng Xiao, Mike Lewis, Wen-tau Yih, Luke Zettlemoyer, and Pang Wei Koh. Context Language Models. September 2026. URL: https://arxiv.org/abs/2609.37725v1 (visited on 2026-10-16), arXiv:2609.37725v1. ↩