Harness Engineering Anatomy, Architecture, and Evolution of Coding Agents
A source-code comparison of eleven agent harnesses and the seven parts they have in common.
A source-code comparison of eleven agent harnesses and the seven parts they have in common.
An ablation of planning, tools and context management configurations for coding agents.
A new benchmark that tests whether AI agents can follow long company policies during realistic work
An LLM-judge approach that brings interpretability and actionability to your scores.
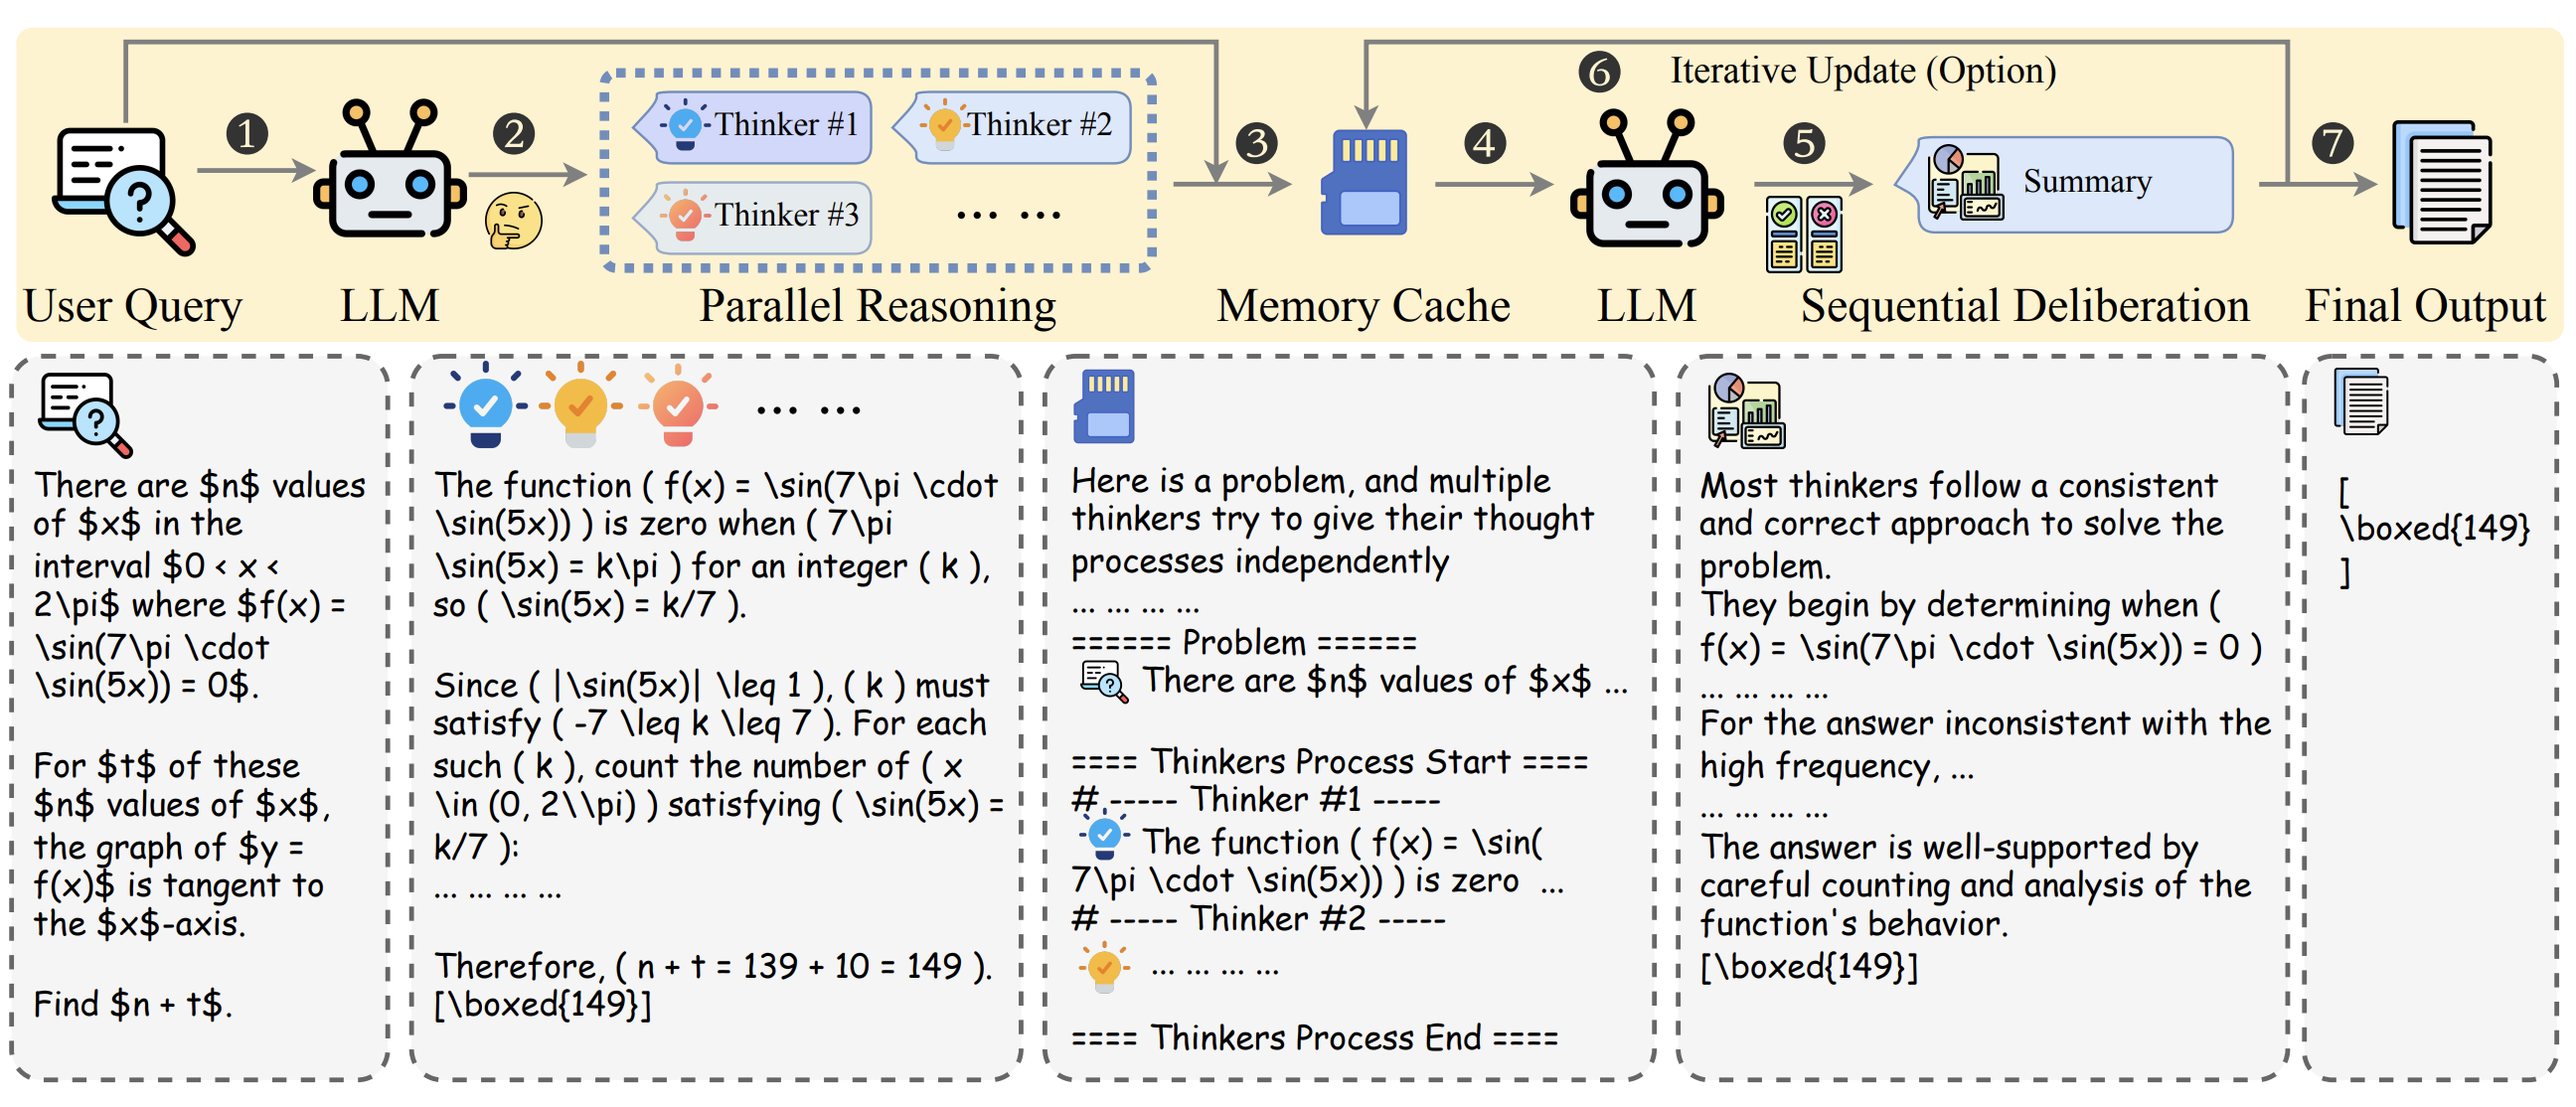
Now we have GPT Pro at home

A large-scale study on long-horizon document tasks.
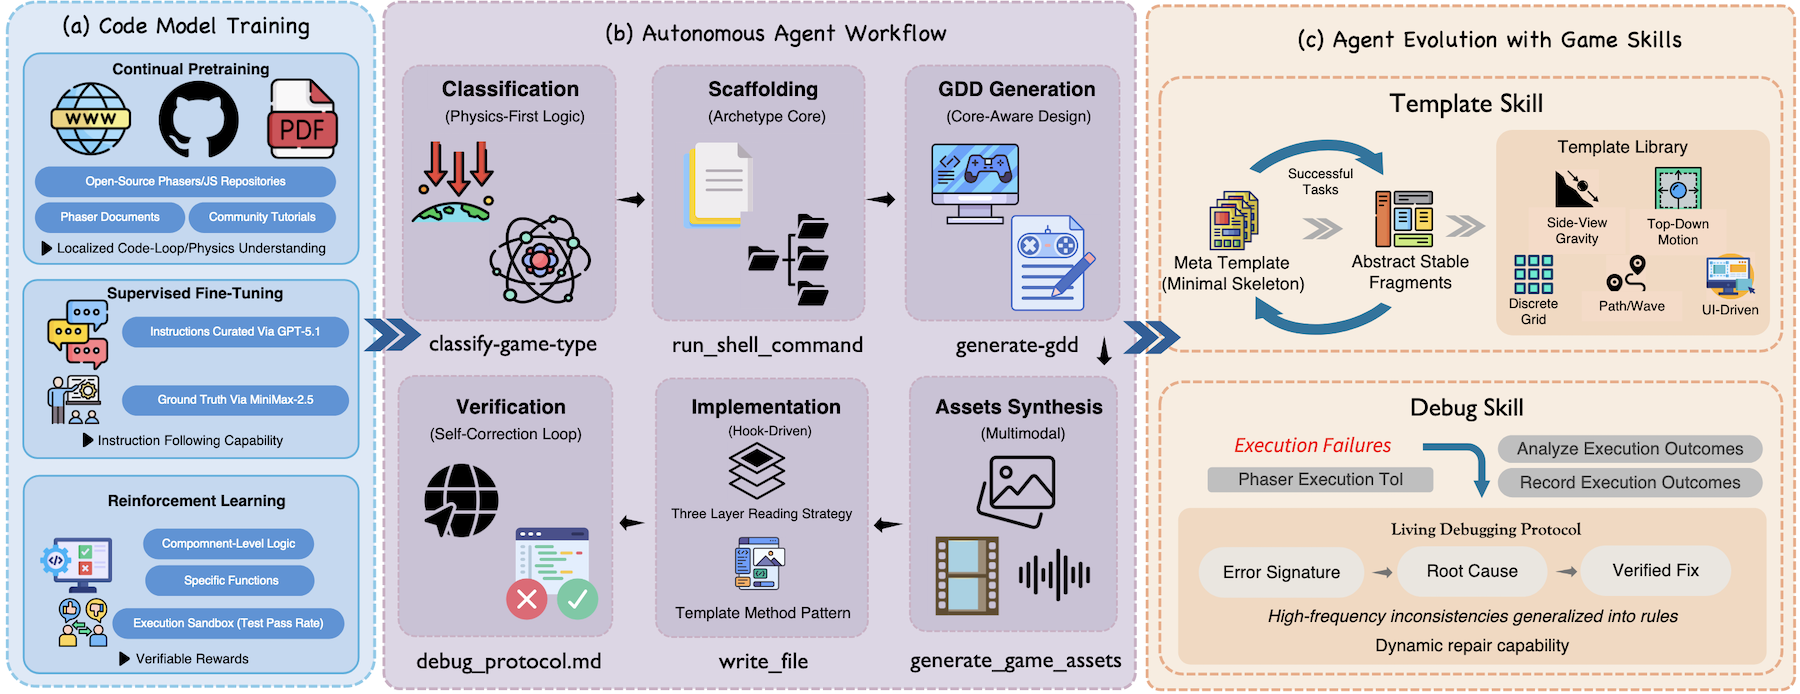
An agentic framework for end-to-end game creation
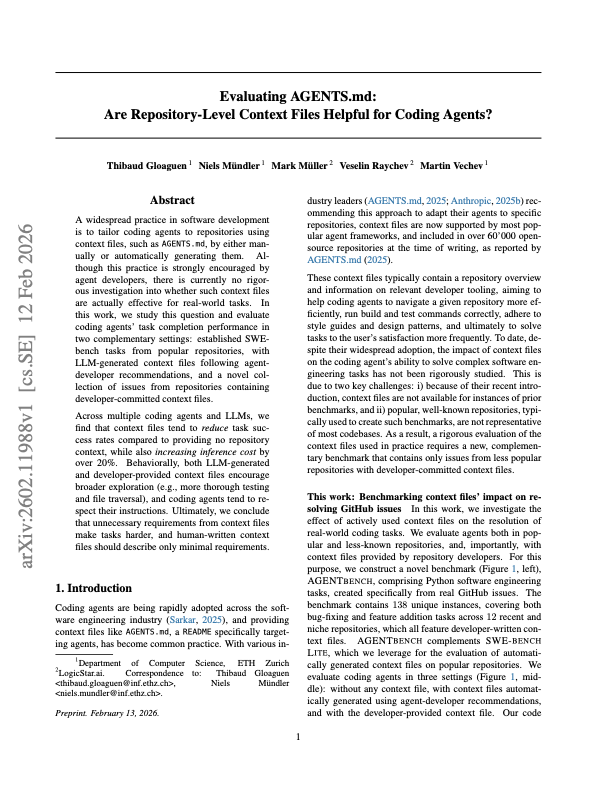
Self-generated agent context files don't help.

Curated skills boost agent performance by 16 points; self-generated ones don't help at all.
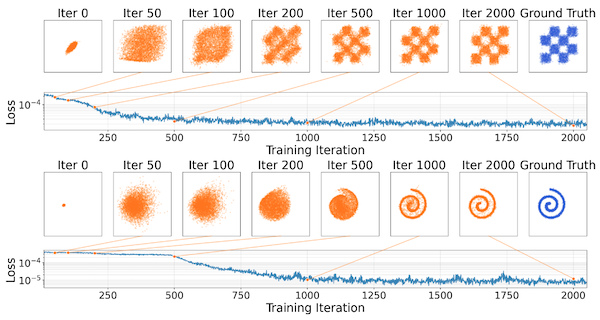
A new paradigm for single-step generative modelling